
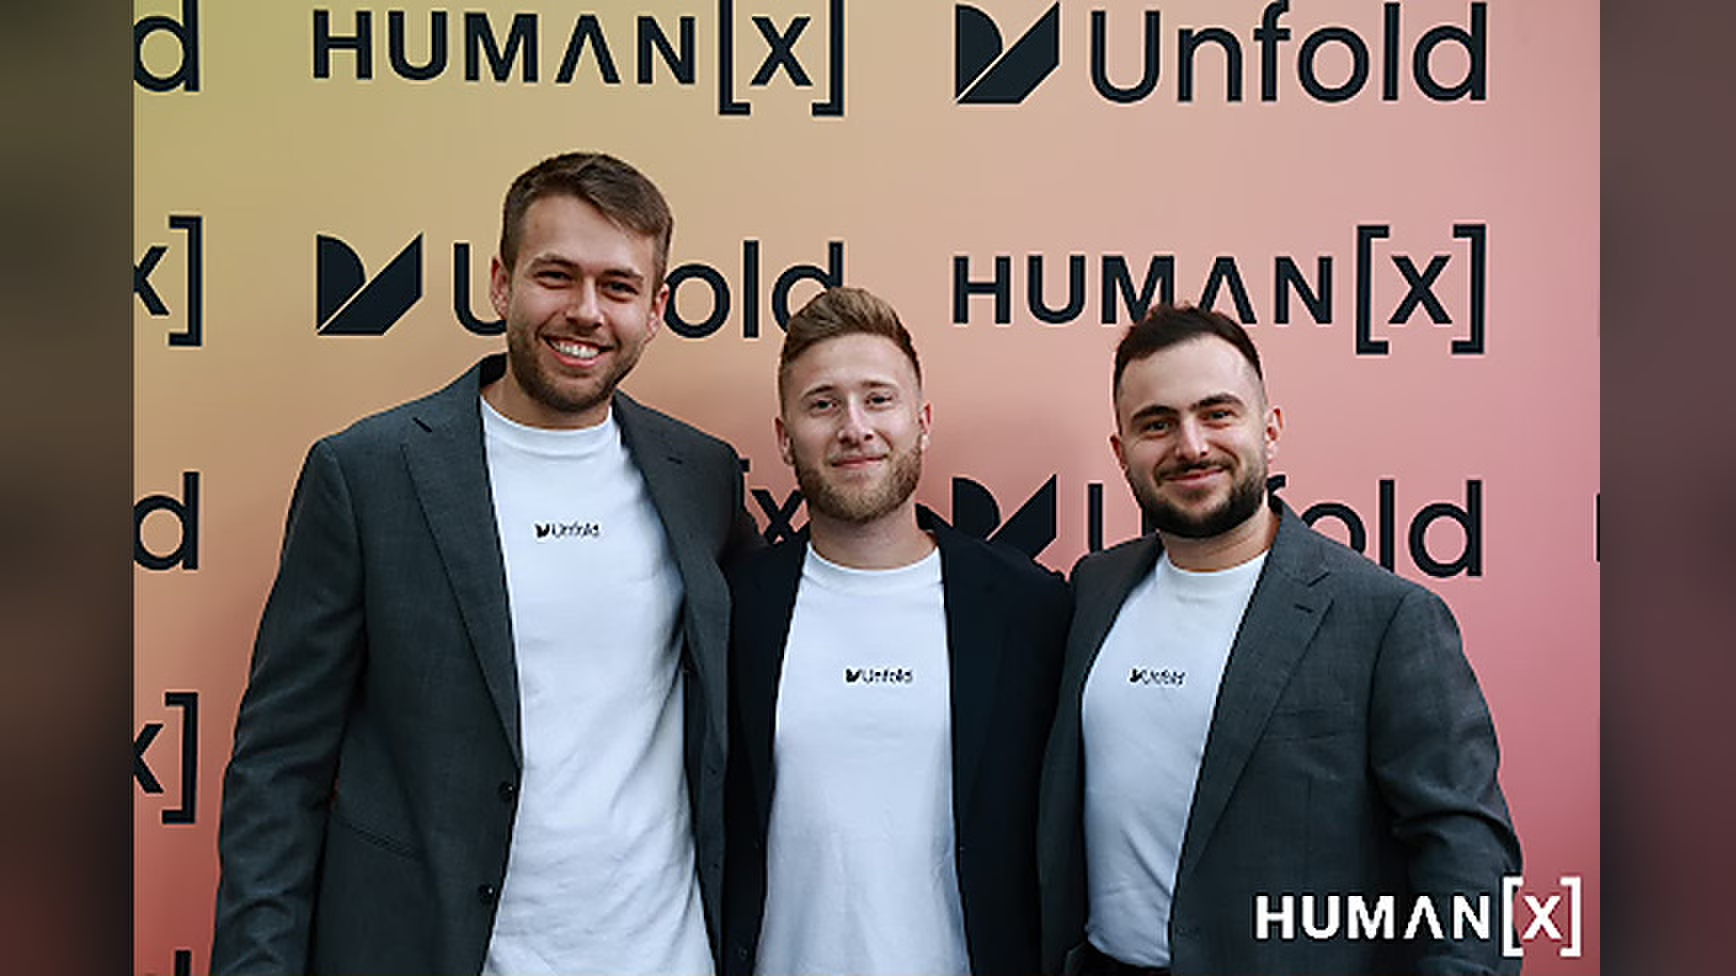
Credit: HumanX/Unfold As enterprises accelerate AI adoption, a major obstacle remains: much of the data AI needs is still trapped inside legacy systems, proprietary software, and applications that lack modern interfaces. Traditional integration tools have helped connect enterprise systems, but they often cannot access the full scope of information or capture the business context needed to make that data useful. For Ran Cherniavsky, CEO and Co-Founder of Unfold, the solution is to rethink how enterprises access their data. Unfold works through the interfaces businesses already use, extracting information and mapping the underlying logic without requiring system replacements or disruptive migrations.
In this Q&A, Cherniavsky discusses why data accessibility is becoming a defining challenge for enterprise AI, how Unfold unlocks information from otherwise closed systems, and what becomes possible when AI agents can finally understand the full picture of an organization’s operations. The enterprise data problem 1. Why do so many enterprises still struggle to access critical data trapped inside closed systems, despite years of investment in integration technology? Because integration was built for systems, not for AI.
It connected system A to system B, one field at a time, through whatever the vendor chose to expose. AI needs access to everything a human being can see in a system, and an understanding of what it means. And it needs it fast, without a project for every field. That’s a different problem. 2.
What are the biggest risks and business costs of leaving data locked inside systems that lack APIs or other standard interfaces? Companies that can’t put AI on their core data will fall behind the ones that can, and that gap opens fast. The costs show up long before that. Companies pay specialized consultants, year after year, to map a system’s fields by hand.
Analysts pull capped reports manually and stitch them together in Excel. AI pilots stall because the model only sees the slice the API exposes, and gets the answers wrong. In effect, you’re renting access to your own data through someone else’s UI. And there’s a risk you can’t see: if nobody can read what’s inside a system, nobody can be confident it’s secure either.
You’re left hoping. 3. Between security, IT modernization, and AI adoption, where does inaccessible enterprise data create the biggest problem today, and why? AI adoption, and it’s not close. That’s where the pressure from the board is, and that’s where locked data costs you right now.
You can’t just open Claude and ask, “A dealership owner can’t ask Claude how old the warranty money owed to him is, because that data is stuck behind reports?” Not because you can’t write the question in plain English, but because the data isn’t accessible. Security and modernization feel the same problem, but differently. Security is a symptom: you can’t secure what you can’t see. Modernization is the long way around.
According to Gartner, 45% of core systems still run on mainframes or on-prem client/server, and 34% of organizations now leave core applications as they are because modernizing them is too risky. AI can’t wait for that to change. Solve access and context for AI, and you’ve solved a big part of the other two along the way. Unfold’s technology and differentiation 4.
How does Unfold access systems that have no APIs, exports, or open interfaces? The same way a person does. Employees don’t work with a system only through its API. They use the UI, reports, exports, files and more.
Unfold works through every interface the application exposes, with or without an API. Our team spent years doing deep software research, integrating with systems regardless of what they exposed. That used to take months per system, by hand. With AI, Unfold becomes the subject-matter expert on a system in days, maps where every piece of data lives and how it moves, and then builds a deterministic read-only collector that gets it out through the system’s own permissions.
That works on mainframes like AS/400, on-prem ERPs, and modern SaaS that only exposes part of its data. If a system has a UI or a command line, we can work with it. Onboarding takes up to 14 days, for any system. 5. How does Unfold understand the context behind a system’s data, rather than simply extracting the raw data?
Raw data without meaning is noise. In Oracle’s ERP JD Edwards, tables carry numbers instead of names. A status field holds a code nobody remembers defining. Two systems call the same customer by different names.
Unfold learns each system the way a trained employee would: what each object means, how objects relate, which business rules and exceptions apply, and how people actually use it. Because we see the screen and what sits underneath it, we can tie what a user sees in the UI to where it lives in the data. That knowledge used to live with SMEs, implementation partners and vendors, and much of it walked out the door. We rebuild it as a catalog of every data object, with its business meaning and its full journey through the system.
AI gets the data and the context together, and stops guessing. 6. How do you ensure that data from different enterprise systems is normalized, governed, and ready for AI applications? Once each system is understood, we connect them. The same customer is KUNNR in SAP and an Account in Salesforce.
The same site has a different ID in each ERP. Unfold maps all of it into one canonical enterprise schema, so data from every system arrives normalized and consistent. Governance is built in from the start. The data stays with the customer, in their own source systems.
Lineage comes with it, because we know where every field came from and how it was transformed. And the collectors are deterministic: the same question returns the same data every time. That’s what you need before you let an agent act on it. 7. How does Unfold complement existing platforms like Splunk, Snowflake, and Databricks, and what makes its approach different from traditional integration tools?
First, we don’t replace data platforms; we feed them. Splunk, Snowflake and Databricks are where data gets searched, analyzed and put to work by AI, and they’re only as good as what reaches them. Today, that’s whatever a source system’s API or export allows. And you don’t have to move the data at all: Unfold can work with it where it lives, in the source systems, or deliver it straight to agents through our connector to Claude, Gemini and others.
Unfold sits upstream. We get the data and the logic out of the systems that never fed those platforms, with the meaning attached, and deliver it wherever the customer needs it: their lake, their warehouse or their agents. At a global retailer, point-of-sale data from an AS/400 mainframe is heading into a Gemini Enterprise fraud-detection agent. At a manufacturer, plant control system data is heading into a CMDB.
Traditional integration starts from a catalog of prebuilt connectors and moves what each vendor exposes, one project at a time. Unfold starts from the system itself: every interface, the full data model and the business context, in days rather than months. Customer applications and business impact 8. What are the most compelling real-world use cases for Unfold, and how do customers measure the value of unlocking previously inaccessible data?
The best use cases start the same way: someone sees data in a screen and can’t get it into the workflow they need. A few examples: A global retailer needs point-of-sale data from AS/400 systems in more than ten countries feeding its fraud detection, which now runs on Gemini Enterprise. One country’s regulator told them to stop selling until that control was in place. A top-10 US insurer pays contractors with specialized expertise to map claims-system fields to the database by hand.
Then another team of engineers comes in to build the ETL

Leave a Reply